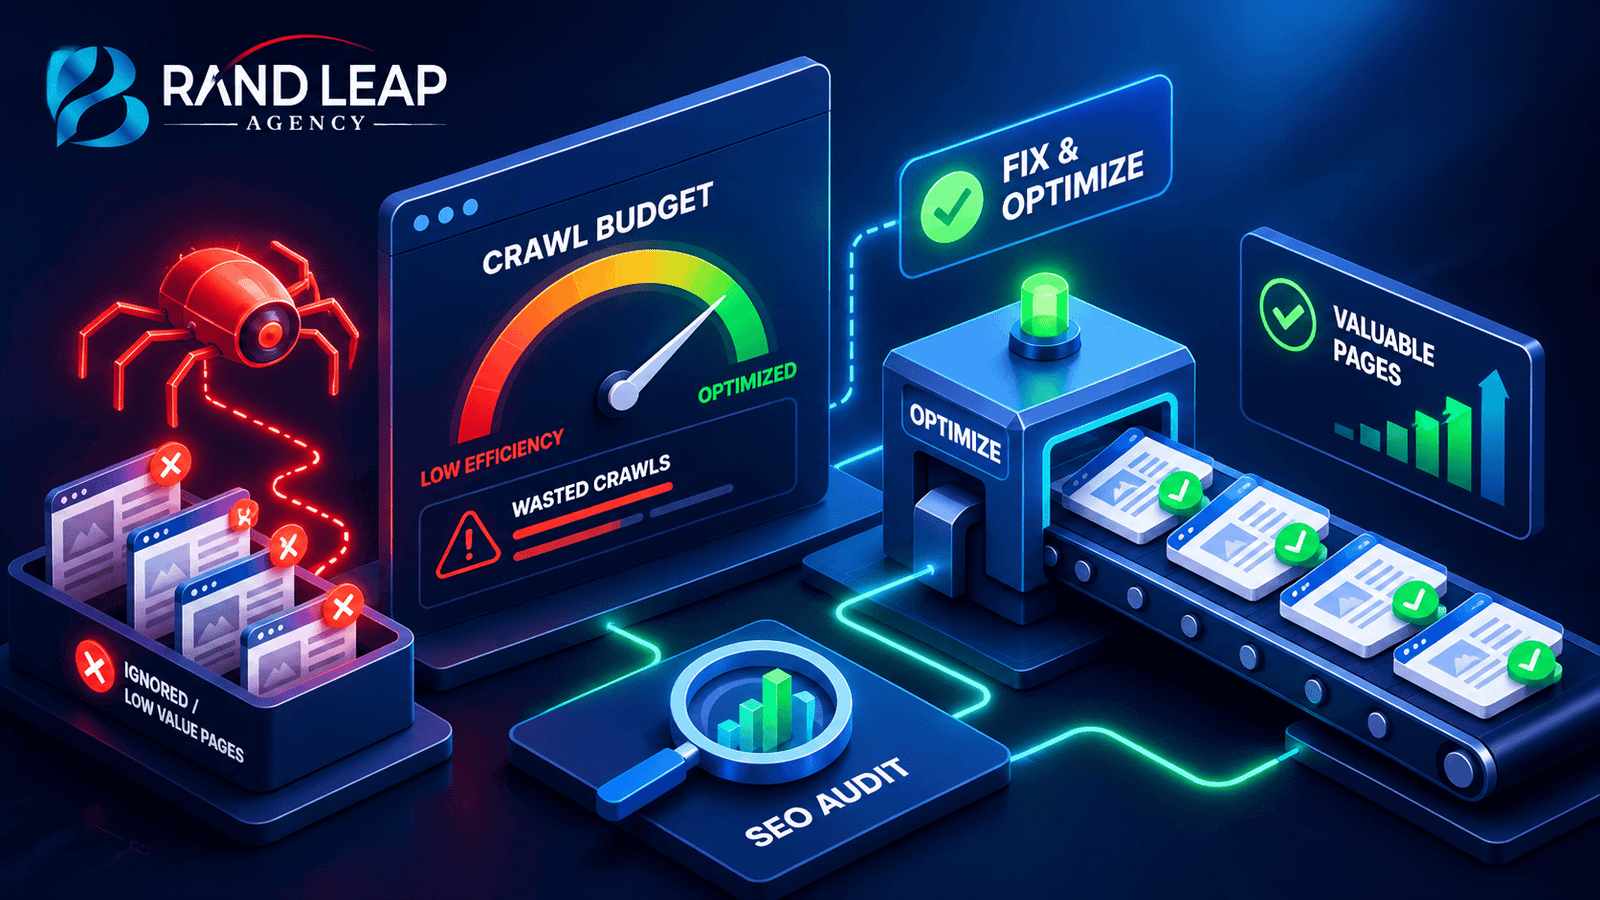
Crawl budget optimization is the practice of directing Googlebot toward the pages on your site that can rank and steering it away from URLs that waste its limited crawl visits. Google doesn’t assign you a fixed number of crawl requests per day. Instead, it balances two factors: how much your server can handle and how much Google wants to visit your URLs based on their quality and popularity. For very small sites with under a few thousand indexable URLs, crawl budget is rarely a limiting factor. But for any growing website with product filters, a blog archive, a tag taxonomy, or thousands of URLs, crawl budget becomes a quiet indexing bottleneck that compounds over time.
The stakes are straightforward: pages that aren’t crawled can’t be indexed, and pages that aren’t indexed don’t drive organic traffic. In the structured SEO audits Brandleap Agency runs for clients who assume their site is performing well because it “looks good,” crawl budget waste turns up repeatedly as a core technical finding. If new content takes weeks to appear in search or rankings seem stuck despite solid content, a crawl efficiency problem is often the culprit. The sections below show how to find it and fix it.
Key takeaways
- Two factors control crawl: Google combines your server’s capacity to handle requests with its own assessment of how much it wants to visit your URLs.
- Size matters for diagnosis: Sites with fewer than a few thousand URLs rarely hit crawl constraints; the issue surfaces at 10,000-plus URLs, especially with faceted navigation or heavy parameter use.
- Waste has predictable patterns: Duplicate URLs, parameter sprawl, redirect chains, and thin content returning 200 status codes are the primary offenders.
- Three tools, three distinct jobs: robots.txt, XML sitemaps, and noindex directives each serve a distinct purpose and shouldn’t be used interchangeably.
- Measurement confirms progress: Track your wasted crawl ratio before and after changes using Google Search Console and server logs, not guesswork.
What is a crawl budget, and how does Google calculate it?
Google determines how much to crawl your site by combining two signals. The first is crawl capacity: how many requests your server can handle before it slows down or starts returning errors. The second is crawl demand: how much Google actually wants to visit your URLs based on their popularity, freshness, and discoverability. Both signals must be healthy for efficient crawling to happen.
How your server health sets the crawl ceiling
Think of server capacity as the ceiling your site sets for itself. Fast, stable responses allow more parallel Googlebot connections and therefore more crawling. Slow response times, frequent 5xx errors, and 429 rate-limit responses all cause Googlebot to back off. This isn’t something Google imposes arbitrarily; your server’s behavior directly determines how aggressively Googlebot is willing to return. Google adaptively reduces crawl rate in response to elevated error rates and degraded server performance, so monitoring your median and p95 TTFB alongside server error rates gives you the clearest picture of where your crawl ceiling actually sits.
How popularity and freshness drive crawl demand
On the demand side, Google prioritizes URLs with strong inbound links, frequent content changes, and a clean discovery path through sitemaps and internal links. A large inventory of low-value URLs, including parameter variants, duplicate paths, and expired listings, spreads demand thin and pulls Googlebot’s attention away from the pages that matter. This is the core of the crawl budget problem: it’s not that Google ignores you; it’s that it burns visits on the wrong pages.
Does your site actually have a crawl budget problem?
Not every site needs to worry about this. If your business has 20 clean pages and a straightforward architecture, crawl efficiency is almost certainly not limiting your growth. The self-diagnosis step matters because the fixes require real technical effort, and applying them to a site that doesn’t need them wastes time better spent elsewhere. Combining the second and third points: if you’re unsure whether your site crosses the threshold where crawl budget becomes a concern, check your URL count and architecture before investing in remediation.
The site types where crawl waste shows up most
E-commerce sites with faceted navigation are the most common offenders. Five sort options combined with four view modes and three availability filters can generate sixty-plus URL variants of a single product grid page. Blogs with tag pages, author archives, category pagination, and internal search result URLs face the same problem at a different scale. Any CMS that auto-generates parameterized URLs without restriction creates this issue by default. The symptoms are consistent: important pages take weeks to get indexed after publication, and new content simply doesn’t appear in search results on any predictable timeline.
How to check crawl activity in Google Search Console right now
Go to Settings, then Crawl Stats in GSC. You’re looking for three things: total requests over the last 90 days, the response-code breakdown showing how many 3xx, 4xx, and 5xx responses Googlebot received, and the average response time. Then cross-reference with the Pages report under Indexing. Count submitted URLs versus indexed URLs. A large gap between those two numbers is your warning sign that something is eating crawl budget before Googlebot reaches your priority pages.
Crawl budget optimization starts here: identifying where crawl budget is going.
Most crawl budget problems trace back to a small set of predictable sources. Knowing which category your waste falls into determines which fix applies, and applying the wrong fix can make things worse.
Duplicate pages and URL parameter sprawl
The same content accessible at multiple URLs multiplies your URL space without adding indexable value. HTTP versus HTTPS, trailing slash versus none, www versus non-www, sort and filter parameters: each combination creates another URL that Googlebot may visit. In GSC’s Pages report, look for “Duplicate without user-selected canonical” and “Alternate page with proper canonical tag” in the exclusion reasons. A high count under either of those categories tells you that Google is finding more duplicate surface area than your canonical strategy is controlling.
Thin content and soft 404s Googlebot keeps revisiting
Thin content in this context means tag pages with one post, expired promotion pages returning 200 OK, empty category pages, and internal search result pages with no meaningful copy. Google keeps crawling these because they return a successful status code, even though they offer nothing worth indexing. The audit step here is sorting the GSC Indexing report by “Crawled but not indexed” and reviewing the reason codes for patterns across URL types. If you see a cluster of URLs from one template repeatedly showing up there, that template is the problem.
Redirect chains and broken internal links
Each redirect hop uses a crawl request without delivering an indexed page. A chain of three redirects consumes three requests to reach one URL. Broken internal links send Googlebot to 404 pages, burning crawl budget without delivering a returnable page. Run a site crawl with a tool like Screaming Frog to identify chains longer than one hop and internal links pointing to missing pages. Flattening chains to a single direct redirect and repairing broken links are two of the highest-return fixes available, and they’re technically straightforward.
The practical fixes: robots.txt, sitemaps, and noindex
Once you’ve identified which URL types are eating your crawl budget, three tools handle containment. Each serves a different purpose, and swapping them out of context creates new problems.
Robots.txt rules for crawl budget optimization: block junk without blocking assets
Block URL patterns that generate low-value crawl surfaces: internal search results, session IDs, tracking parameters, and unnecessary sort or filter combinations. A practical rule set might include, and Disallow: /*?session_id= while leaving /products/ fully accessible. Never block CSS, JavaScript, fonts, or images. Googlebot needs those to render and evaluate pages properly. A broad rule Disallow: /*? can accidentally remove useful filtered or paginated content from crawling entirely, which causes a different set of indexing problems.
Turning your XML sitemap into a clean priority list
Your sitemap’s job is not to document every URL your site can generate. It’s a curated whitelist of canonical, 200-status, indexable pages. Remove redirected URLs, noindexed pages, parameter variants, and thin content from your sitemap. Only add accurate lastmod dates when content genuinely changed; Google ignores priority and changefreq values them entirely. For larger sites, segment into separate files by content type, such as sitemap-products.xml and sitemap-editorial.xml, so you can monitor each segment’s indexed-versus-submitted ratio independently in GSC.
Choosing between noindex and blocking for different page types
This distinction trips up most site owners. A page blocked in robots.txt cannot reliably receive and act on a noindex directive, because Googlebot may never crawl it to read the tag. Use robots.txt blocks when you want to prevent crawling entirely: session URLs, admin pages, and checkout flows. Use noindex when a page should be crawled and discovered but kept out of the index: thin archives, thank-you pages, and duplicate variants where a canonical already exists. The two tools answer different questions, and mixing them creates situations where Google has no signal at all about what to do with a URL.
How do you know if your crawl efficiency fixes are working?
Making changes without measuring them is guesswork. Before touching anything, save a screenshot of your current Crawl Stats report in GSC. That’s your baseline. After roughly two to six weeks post-fix, depending on site size and crawl frequency, return to the same report and compare: the share of 4xx and 5xx responses should drop, response time should hold steady or improve, and the ratio of indexed to submitted pages in your sitemap should move in the right direction.
For a more precise measure, use the wasted crawl ratio. Divide your error responses (4xx plus 5xx) by total Googlebot requests and multiply by 100. A ratio above 5% warrants investigation. A broader version of this metric counts all wasteful requests, including duplicates and redirect chains, against total requests. In practice, under 10% is generally healthy; above 25% is a significant efficiency problem worth prioritizing, and these are working thresholds used across technical SEO audits rather than hard cutoffs from any single source. The goal isn’t necessarily more total crawl requests. It’s a higher percentage of requests landing on canonical, indexable, useful pages. Reducing total crawl volume while improving that percentage is a win.
Crawl budget optimization is an ongoing discipline, not a one-time fix
Crawl budget issues grow with the site. As new pages are published, new filters are added, and old content accumulates, the URL space expands, and low-value patterns creep back in. The fixes covered here- blocking parameter waste, cleaning sitemaps, resolving redirects, and deploying noindex correctly- need to be revisited on a regular audit cycle, typically every three to six months.
Many site owners notice crawl budget problems only after rankings stall or new pages take months to appear in search. By that point, the issue has been compounding for a long time. A free SEO audit from Brandleap surfaces these exact patterns: which URL families are consuming Googlebot’s visits, which pages are excluded from the index and why, and which crawl budget optimization changes would produce the biggest improvement in the shortest time. It’s the kind of technical visibility most growing websites never surface until a structured audit forces the question. Get in touch with our team to get started.
Frequently Asked Questions
How often should I recheck crawl budget after fixing issues?
You should revisit crawl budget fixes on a regular audit cycle, typically every three to six months. Crawl budget problems grow as new pages and filters are added, so periodic checks prevent low-value URL patterns from creeping back in.
How do I calculate the wasted crawl ratio to measure progress?
Calculate wasted crawl ratio by dividing error responses (4xx plus 5xx) by total Googlebot requests and multiplying by 100. A ratio above 5% warrants investigation, under 10% is generally healthy, and above 25% indicates a serious efficiency problem in audits.
Can very small sites ignore crawl budget concerns?
Very small sites with under a few thousand indexable URLs rarely hit crawl constraints. The issue typically surfaces for growing sites at around 10,000-plus URLs or when faceted navigation or heavy parameter use is present.
Should I block CSS, JavaScript, or images with robots.txt to save crawl budget?
No, you should never block CSS, JavaScript, fonts, or images in robots.txt. Googlebot needs those assets to render and evaluate pages properly, and blocking them can harm how Google assesses your pages.